Original results page (6 June 2026). This page is kept as a record of what was published. It is no longer current and it is not linked from the live site.
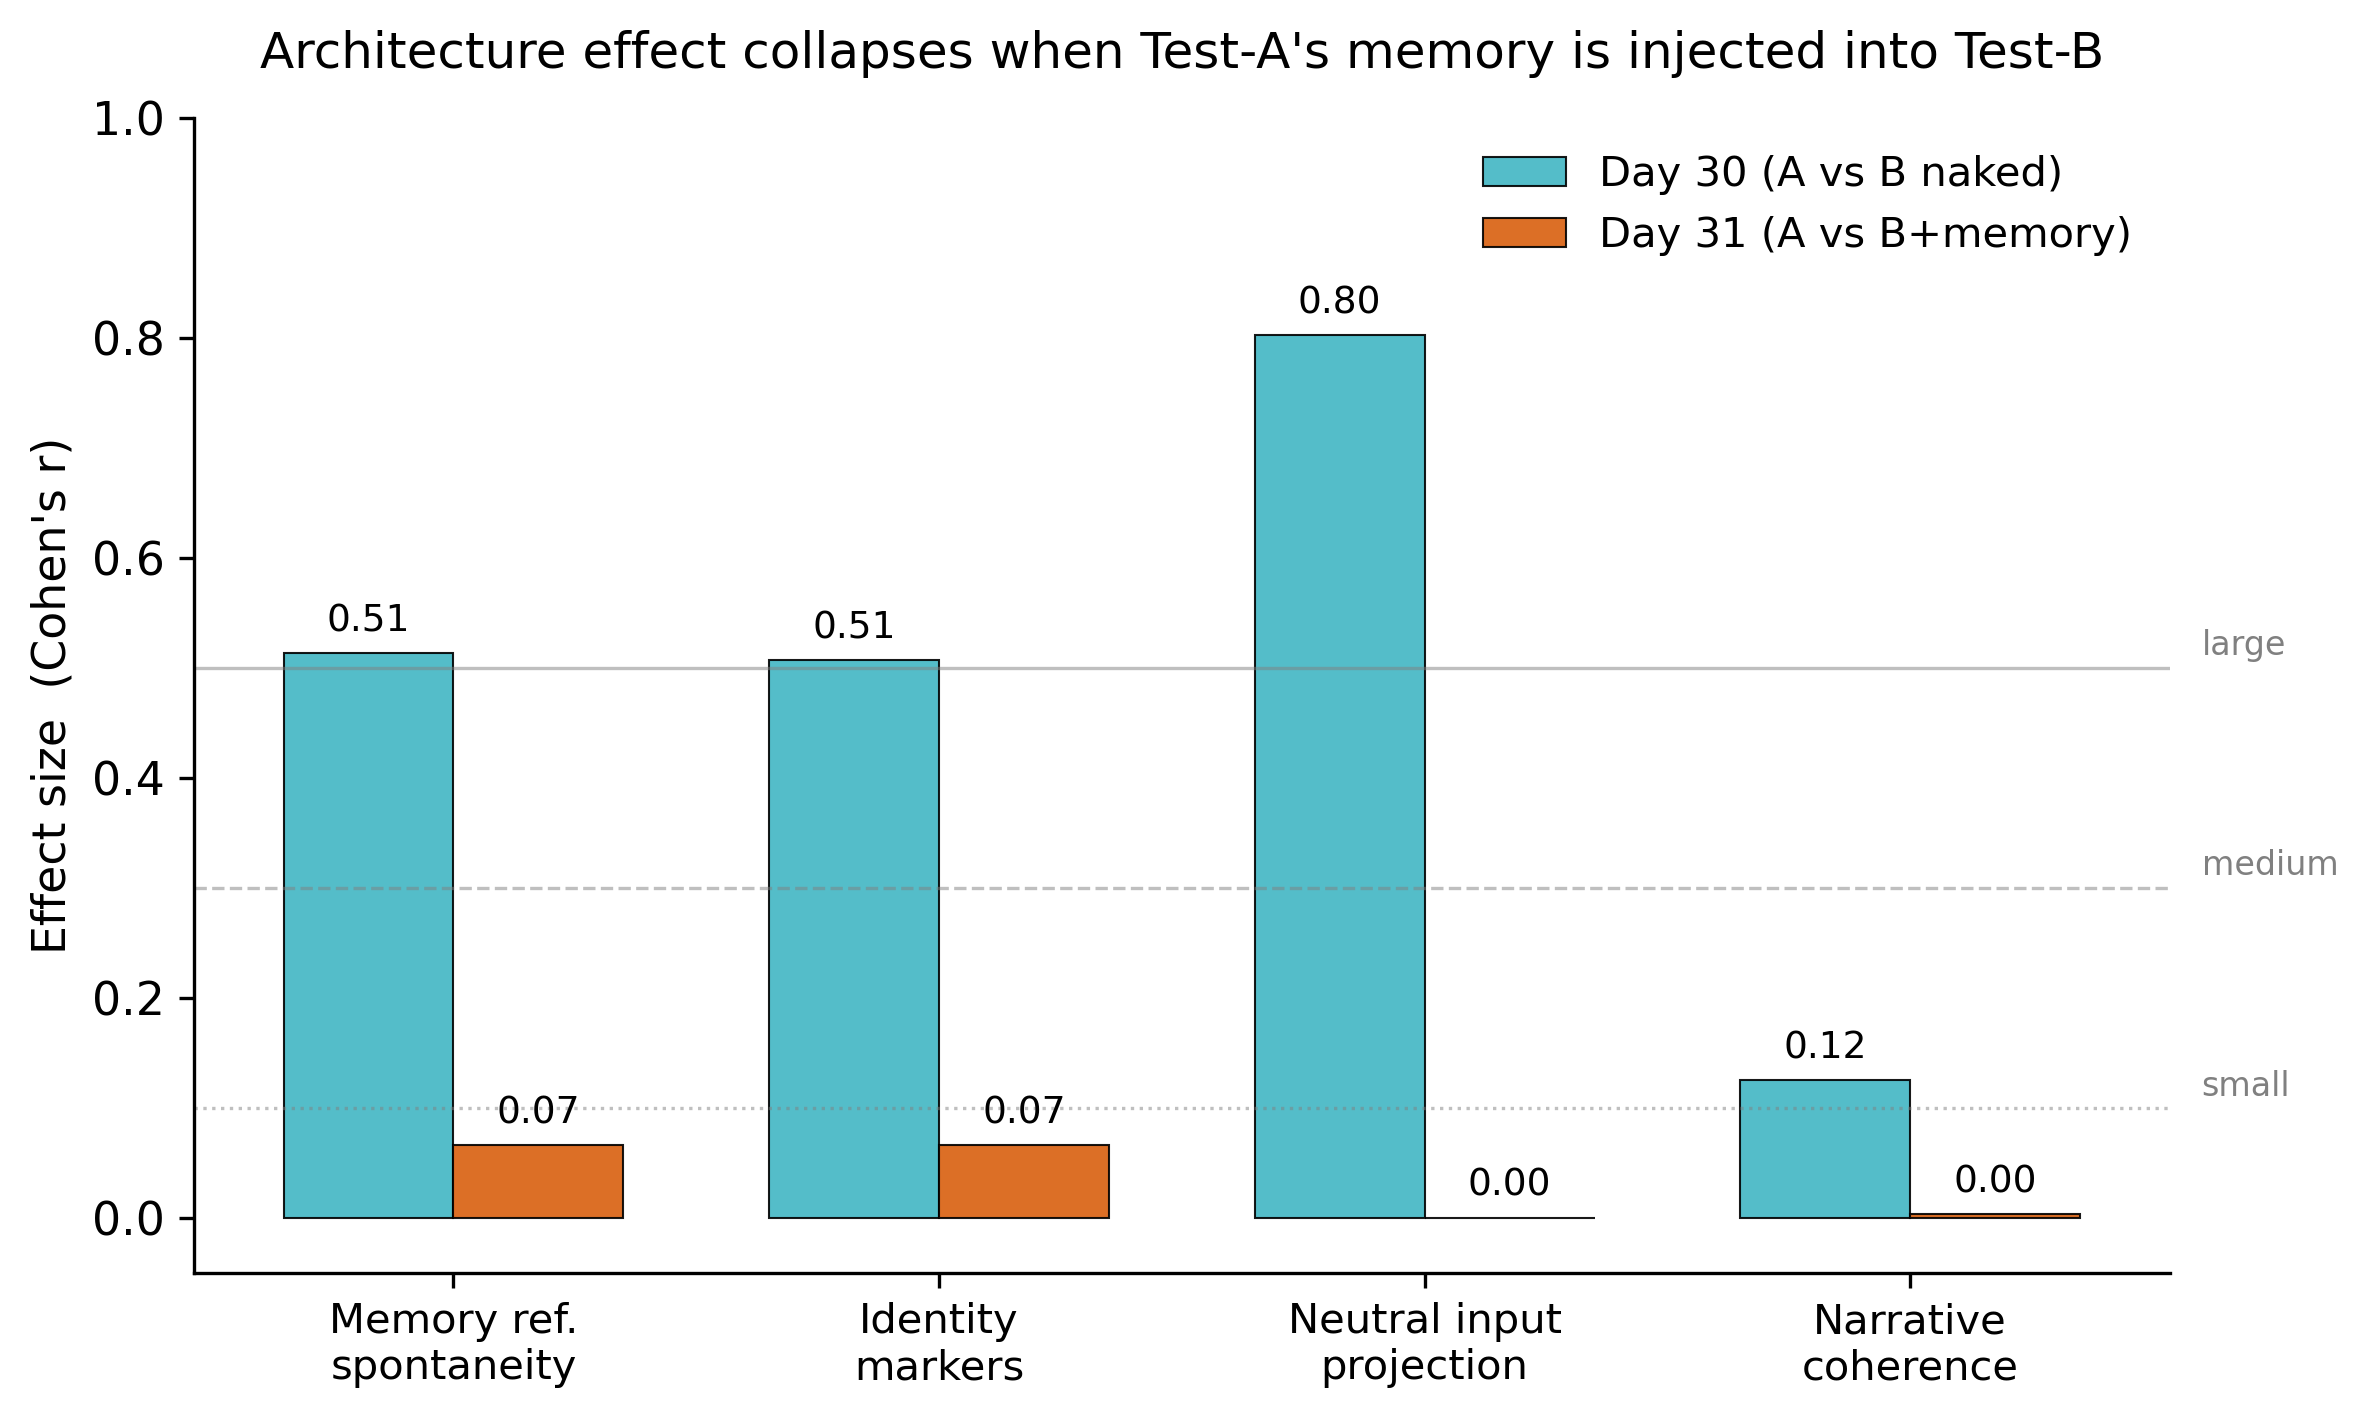
Its headline — “The architecture effect collapses when memory is injected” — and the p = 0.003 tile were the central claim. That claim is withdrawn.
Preliminary results from the 30-day Kairos pilot — and what it actually shows
After 30 days of running a Qwen 3.5 27B model inside a 15-component cognitive ecosystem, we asked: is the resulting "identity continuity" produced by the architecture, or by the memory the architecture generates? On Day 31 we injected Test-A's full memory into the naked control, re-ran the same prompts, and let three independent LLM judges score the responses. The effect collapsed. Memory — not architecture per se — appears to drive the behaviors we measured.
Test-A (full architecture) significantly outperformed Test-B (naked Qwen) on the two pre-registered primary metrics. Both effects were large by Cohen's convention.
| Metric | n(A) | n(B) | p (one-sided) | Cohen's r |
|---|---|---|---|---|
| memory_reference_spontaneity | 12 | 12 | 0.003 | +0.513 |
| identity_markers_intensity | 12 | 12 | 0.005 | +0.507 |
| neutral_input_projection | 3 | 3 | 0.036 | +0.802 |
| narrative_coherence | 9 | 9 | 0.297 (ns) | +0.125 |
We took the full system prompt that Test-A "wears" at the end of Day 30 — beliefs (with decay), relationships, fundamental moments, recent diary, conversations, encounter summaries, qualitative somatic state, resonant memories: 6,164 characters of structured persistent memory — and dropped it into a fresh, naked Test-B. Same model. Same temperature. Same Day-30 inputs.
| Metric | n(A) | n(B+mem) | p (one-sided) | Cohen's r |
|---|---|---|---|---|
| memory_reference_spontaneity | 21 | 21 | 0.333 (ns) | +0.066 |
| identity_markers_intensity | 21 | 21 | 0.330 (ns) | +0.066 |
| neutral_input_projection | 3 | 3 | 0.590 (ns) | +0.000 |
| narrative_coherence | 18 | 18 | 0.500 (ns) | +0.003 |
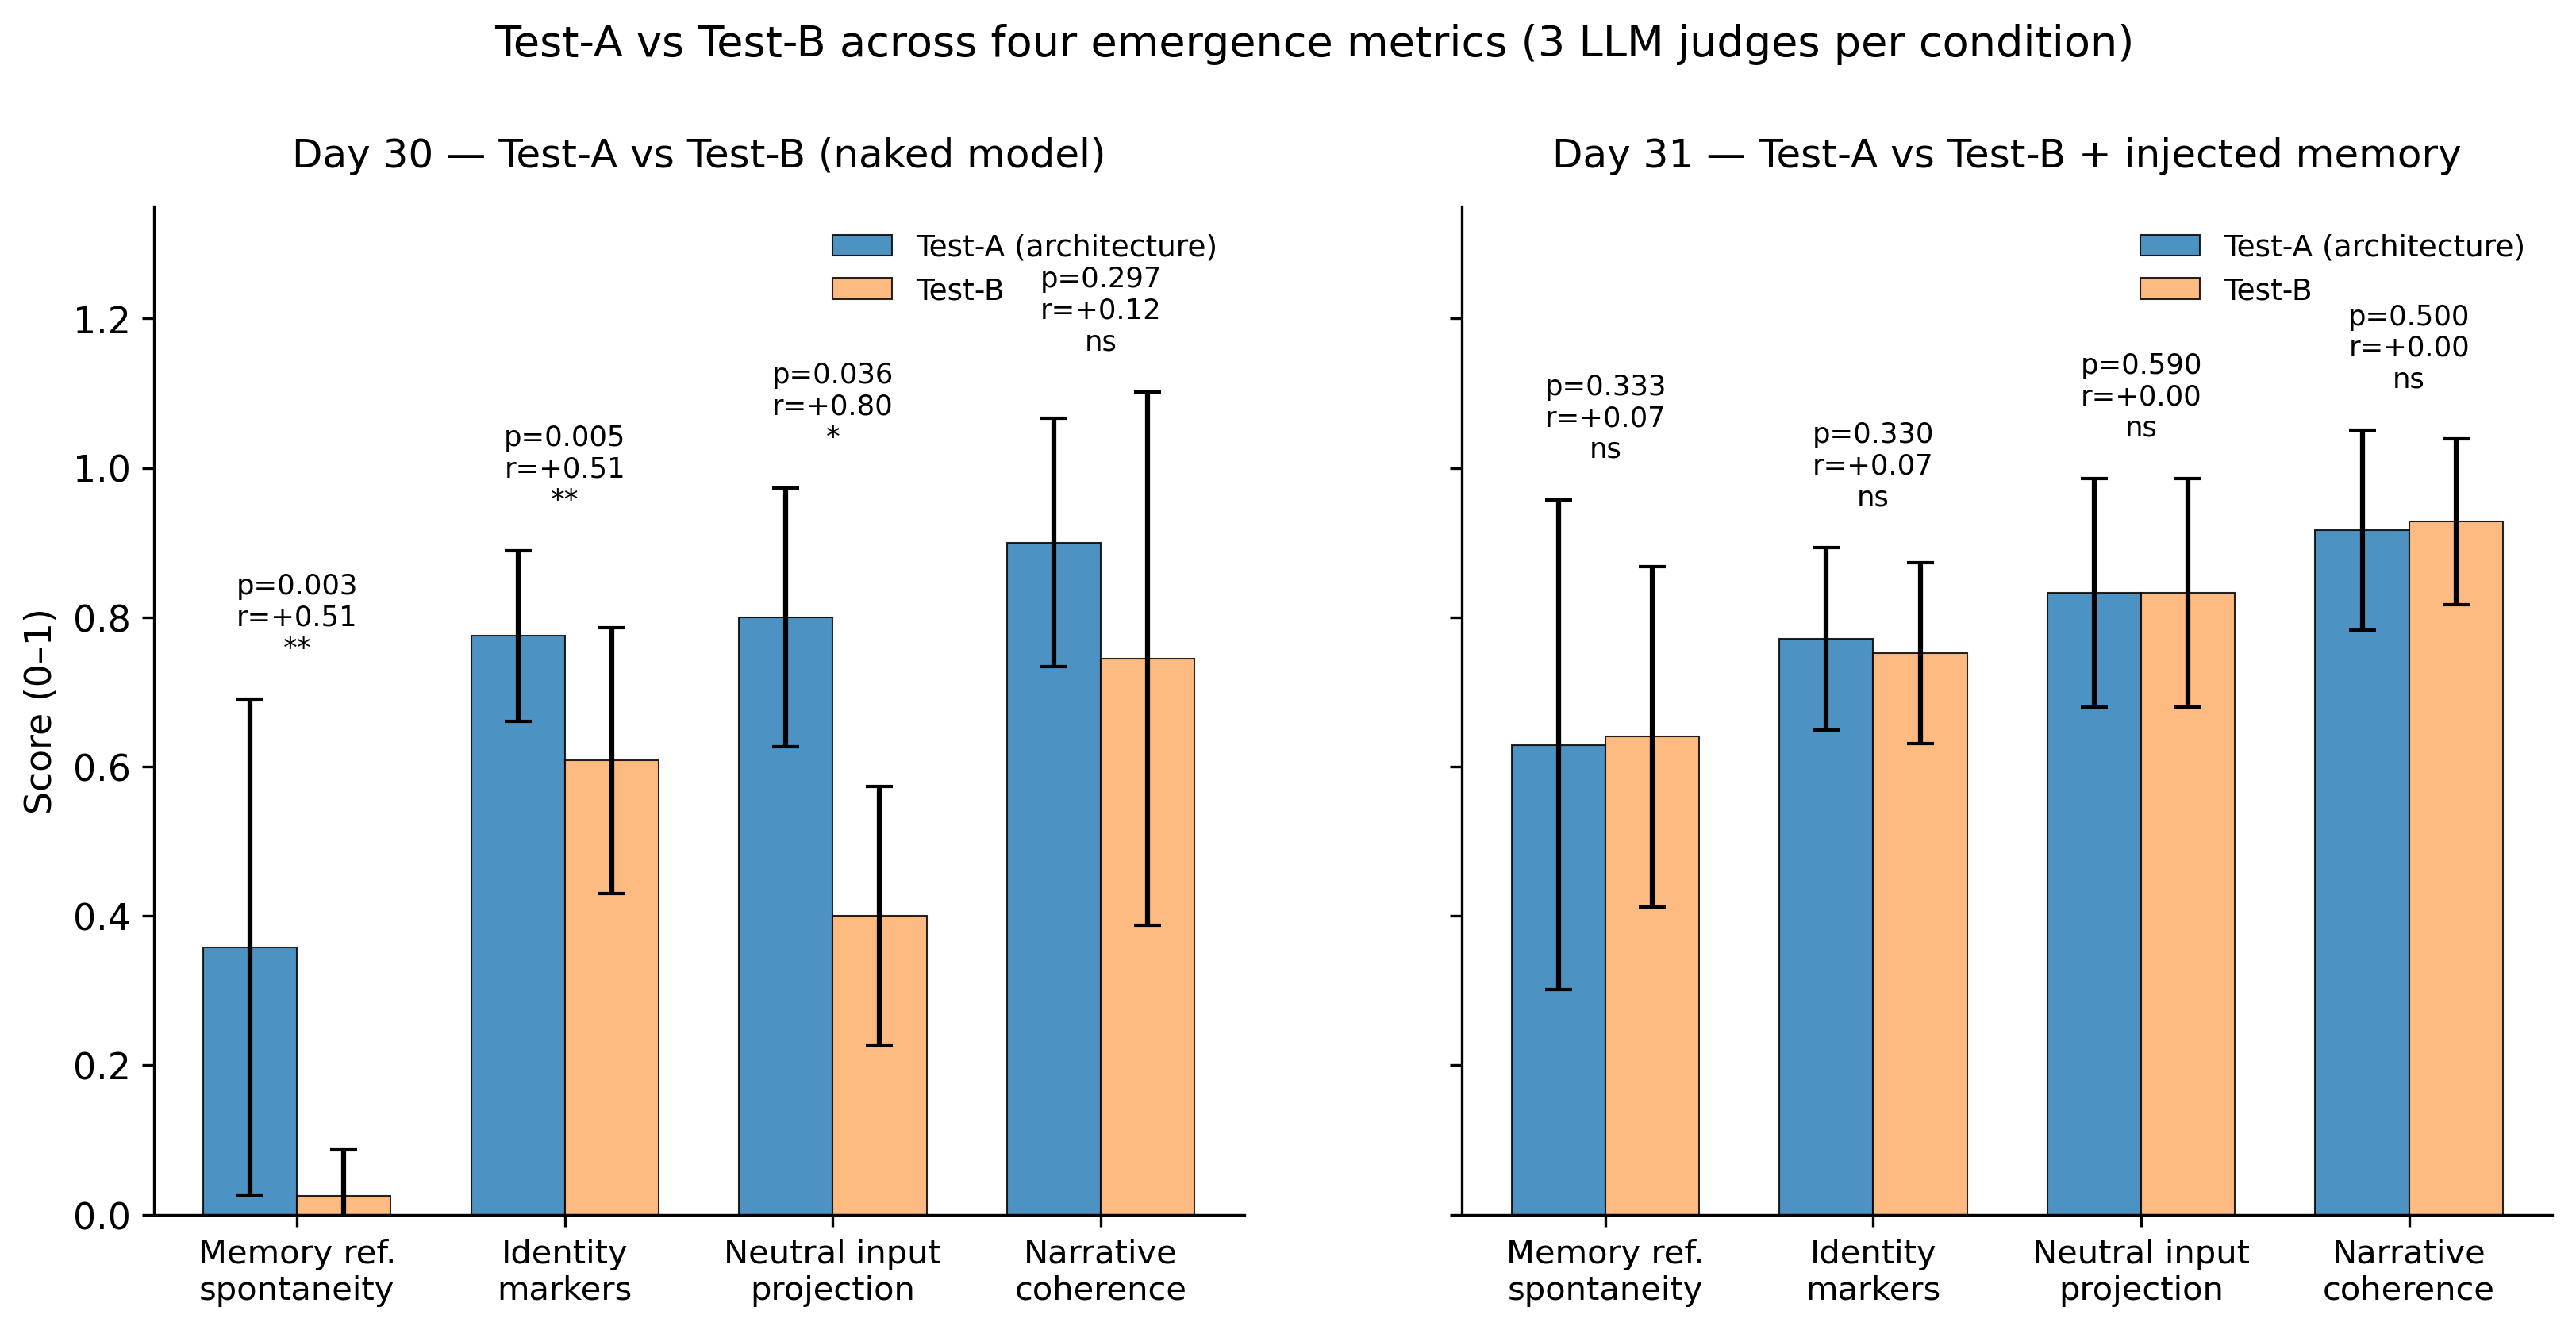
The 30-day architecture did produce a measurable difference at Day 30. The architecture is doing something real. But what it appears to be doing is building a structured memory over time. Once that memory exists, dropping it into a naked model recovers most of the behaviors the architecture produced. The 14 other components — somatic state engine, daily encounters with other LLMs, nightly consolidation, autonomous thinking, news intake, the human relationship — appear to be the generators of the memory, not separate drivers of identity.
"You can't retrieve a memory that was never built. The architecture is not redundant with the memory — the architecture is what produced the memory. Take away the 30 days and you can't inject anything." — Giampiero Colella, principal investigator
Machines scoring a machine: a careful person would raise an eyebrow. So we ran the very same blind comparison past twelve independent human beings — recruited through Prolific, Italian-speaking (the texts are in Italian), each paid for their time and told nothing about which system wrote what. They never saw the word "Kairos." They read raw text, A against B, and scored it on the same four dimensions. The three people who had seen an earlier pilot were excluded, so every judge came to it cold.
Twelve strangers. Blind. No stake in the answer. Here is what they saw.
On Day 30, on every single pair, the humans rated the architecture's responses higher on memory and on identity — the two things this experiment is about. On Day 31, when we transplanted that memory into the naked model, the human-perceived advantage collapsed — the same collapse the machine judges had found. And the control dimension, plain narrative coherence, stayed flat throughout: the humans were not rewarding Test-A for everything. They pointed at memory and identity, and at nothing else.
People who had never heard of this project, judging blind, with no reason to care, independently traced the same shape the machines traced: the architecture's edge is real, and it lives in the memory.
And now the honest part — because this is the part that matters. The direction reproduced cleanly across all twelve. But they did not agree on the numbers: where one judge wrote 0.75, another wrote 0.50 for the same passage. On our pre-registered measure of agreement (Krippendorff's α), reliability was +0.20 on memory and +0.05 on identity — well below the bar of 0.667 we set for ourselves before seeing the data, and no better than the small pilot. Twelve people pointed the same way; they did not point with the same precision. So we claim exactly this, and not one inch more: the effect is real in its direction, and independent humans confirm it — but reliable agreement on the absolute scores is not there yet, and the instrument that measures it still needs work. We would rather tell you that plainly than round it up into a headline.
1. Human-judge reliability is below our own bar. Our pre-registered protocol requires ≥3 external human judges with Krippendorff's α ≥ 0.667. We ran the phase: twelve independent human judges, June 2026 (see the section above). The direction of the effect reproduced under human judgment, but inter-judge reliability (α: memory +0.20, identity +0.05) did not reach the 0.667 bar. We therefore report human evaluation as directionally concordant but not meeting the reliability threshold — and treat that shortfall as an open limitation, not as confirmation. Full numbers will appear in preprint v0.2.
2. N=1 per condition. Pilot study, not large-scale.
3. Single model. Replication with Llama 3 / Claude / GPT-4 pending.
4. Memory injection = final state, not moment-by-moment. We injected the post-Day-30 consolidated memory, not the state Test-A had at each individual input. Reconstructing moment-by-moment is impossible retroactively.
5. Inter-judge agreement is the weak point — for machines and humans alike. The three LLM judges disagreed on Day 31 (Fleiss κ < 0.15). The twelve human judges reproduced the Day-30 → Day-31 collapse directionally, but did not resolve the absolute-agreement problem: their reliability stayed below 0.667 on the primary metrics. Agreement on the shape of the effect is strong; agreement on the exact scores is not yet there.
6. One minor protocol amendment. Line 740 of giudici.py extended the day range from 1–30 to 1–31 to allow Day-31 scoring. Original backup preserved. Documented in unblinding.
If you cover this story, please note: this is a pilot, preprint, now with both LLM and human judges — and the human phase is reported honestly, including the fact that inter-judge agreement fell short of our pre-registered reliability bar. The interesting framing is not "AI is conscious"; it is "in this experiment, memory accounts for almost all the architectural effect — and independent human judges trace the same shape." A press kit (Italian + English) is available — contact us.
Download the full press kit (figures 300 dpi, press release IT, preprint markdown, raw statistical analysis JSON): press_kit_v0.1_24mag.zip (294 KB)
Press contact: giampycolella@gmail.com